Why AI Software Companies Can’t Afford to Skip Step Zero: Protecting the Model Before You Monetize It
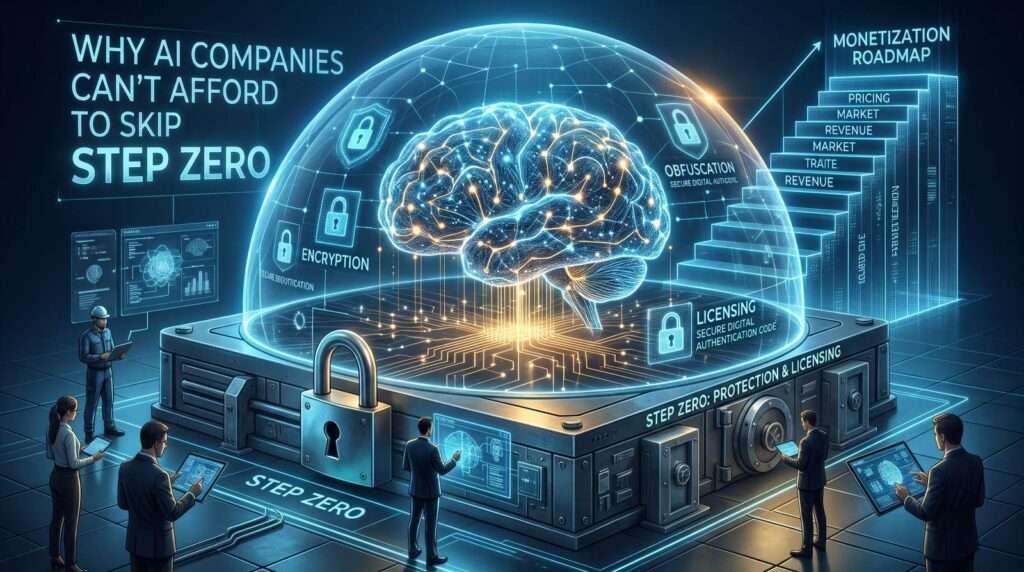
Summary: 42% of companies that have shipped AI products aren’t monetizing them. Most point to pricing or go-to-market as the cause. Real vulnerability is often earlier: an unprotected AI model can be reverse-engineered, extracted, or tampered with — making every downstream monetization strategy irrelevant. This article makes the case for treating IP protection and licensing as Layer Zero of any AI commercialization strategy.
The Uncomfortable Truth About AI Monetization
42% of companies that have shipped AI products aren’t monetizing them. Ask most product and go-to-market teams why, and you’ll hear the same answers: pricing is off, the packaging is too complex, the sales motion isn’t right. Those are real problems worth solving. But there’s a more fundamental vulnerability that rarely makes it onto the post-mortem slide: the model itself.
More than 60% of software vendors have already added AI capabilities to their products, and 76% say AI is leading them to consider new pricing models. But before vendors decide how to charge for AI, they need to make sure the models and capabilities behind those products cannot be copied or used without authorization.
AI models are the culmination of years of training and curated data — a company’s most valuable intellectual property. In edge, on-premises, and embedded deployments, that IP sits directly within reach of anyone motivated enough to look. If it can be reverse-engineered, extracted, or tampered with, no pricing strategy in the world can compensate. A competitor could replicate your solution. An adversary could manipulate your outputs. Users could access capabilities they never paid for.
Before pricing comes protection.
The Hidden Attack Surface of AI Software
Because of the time required to train them, machine learning (ML) models are not typical software assets, making them an attractive target.
The Open Web Application Security Project (OWASP) lists categories of threats particular to machine learning systems. Among the most serious are:
- Model theft and extraction: If the AI tool is running in a location under customer control, such as edge devices, on-premises environments, or embedded systems, attackers can reverse-engineer it and obtain the model itself.
- Model poisoning and transfer learning attacks: An actor who is familiar with the interface between an application and a model can replace a legitimate model with a new one.
- Input manipulation and output integrity attacks: Rather than attacking the model itself, criminals seek to change data fed into or output by the model, allowing them to change any automated decision.
Cloud-based AI services are only partially secured because the model is hosted within the provider’s environment. However, this is not how many production AI systems are delivered. Edge-based systems, SDKs, embedded models, and private cloud-based systems place the model much closer to the user, and from there, the attack surface grows exponentially.
For AI companies, this means that the reality is quite simple: the more useful your model becomes, the more you’ll be targeted.
What “Defense in Depth” Actually Means for an AI Model
Protecting an AI model isn’t a single decision. It’s a set of layered controls that together make extraction, modification, or misuse economically impractical for an attacker.
The most critical layer is encryption at the model itself. An encrypted model is effectively useless without the corresponding decryption key. Even if an attacker gains access to the model file, they cannot read, run, or replicate it. Encryption also provides a secondary benefit: integrity verification. A tampered-with or replaced model will fail decryption, making substitution attacks detectable before they cause damage.
Encryption alone isn’t sufficient. The interfaces and algorithms surrounding the model also need protection. Code obfuscation increases the cost of static analysis, making it significantly harder to reverse-engineer the model’s structure or calling patterns. Anti-debug and anti-tamper measures add a further barrier against dynamic analysis, the kind of probing an attacker would use to map the model’s behavior at runtime.
Not every component requires the same level of protection. The strongest controls should be concentrated on the crown jewels: trained weights, proprietary algorithms, and retraining logic. Lighter techniques are often appropriate elsewhere, particularly where latency or performance is a constraint.
In edge and embedded environments, where the model runs on hardware that the vendor doesn’t control, an additional layer of trust is needed. Signed licenses, hardware roots of trust, and secure key storage ensure that only authorized systems can decrypt and execute the model, regardless of the environment it’s deployed in.
Two AI Companies That Protected Their Models First
Companies shipping production AI are already confronting these risks, and the ones that get it right tend to share a common instinct: protect the model before you build the commercial layer on top of it.
Consider an AI company in the acoustic recognition space. Their core product, software trained to identify specific sounds and trigger automated responses, took years to develop. The model itself, including its retraining logic and parameter values, represented the bulk of their competitive advantage. The problem was that the platform was built in Python, a language widely used in ML development but notoriously straightforward to reverse-engineer without additional protection. Left unprotected, the model and its underlying algorithms were exposed to extraction.
The company addressed this by implementing encryption and obfuscation at the model layer, protecting parameter values, retraining algorithms, and source code from static and dynamic analysis. Only once that foundation was in place did they turn to licensing and packaging. The sequence mattered: protection was the prerequisite, not the afterthought.
A different challenge faced an AI recognition vendor whose software was distributed as SDKs integrated directly into customer hardware, which were deployed in environments where the customer owned and controlled the infrastructure. In that context, software-only protection wasn’t sufficient. The risk wasn’t just extraction; it was unauthorized copying and redistribution across devices the vendor had no visibility into.
Their answer was hardware-based licensing, binding each deployment to a specific physical device. This approach prevented IP piracy while simultaneously enabling feature-based access control. Customers could access only the capabilities they had licensed, with the enforcement enforced at the hardware level rather than relying on the customer’s environment to be trustworthy.
Both cases illustrate the same underlying principle: the goal isn’t to protect code for its own sake. It’s to maintain control over how, where, and by whom your AI is used, which is ultimately what makes monetization possible at scale.
Licensing As the Control Layer on Top of Protection
However, it is not enough to simply protect it. Once a model is protected, it is necessary to have a mechanism to control access to it. This is where licensing comes into play as a means of operational control.
A licensing system determines which users, devices, or applications are allowed to use a model or a specific function within it. For AI vendors, this is important for both security and monetization strategies.
For example:
- Device or environment restrictions: These ensure that a model is only executed on a particular device or environment
- Feature entitlements: These allow customers to access particular features
- Usage limits: These may restrict the number of times a model is executed
Usage controls can also deter model extraction tactics. If a rival attempts to use your application to run massive datasets for their training, rate limits and execution limits can prevent this.
Additionally, licensing platforms have operational advantages, including audit trails based on activation records, use tracking, and management.
New licensing infrastructure may also include self-service portals that help limit the organization’s operational burden while enabling full control over model access.
Protection and Licensing Are the Foundation of Monetization
Protection and licensing aren’t the final steps in building an AI product; they’re the first. Encryption secures the model. Licensing controls who can access it, on which devices, and under what conditions. Together, they form the foundation on which every pricing decision, packaging tier, and go-to-market motion is built. Without them, sophistication elsewhere in the commercial stack is largely irrelevant.
The question every AI software company should be asking before they finalize their pricing model isn’t “what should we charge?” It’s simpler and more urgent than that: if a competitor could reverse-engineer our model tomorrow, what would be left of our business?
For companies building the next generation of AI applications, the answer to that question will determine whether their innovation becomes a durable business or simply a competitor’s next feature.
About the Author
Kirsten Doyle has been in the technology journalism and editing space for nearly 24 years, during which time she has developed a great love for all aspects of technology, as well as words themselves.
Her experience spans B2B tech, with a lot of focus on cybersecurity, cloud, enterprise, digital transformation, and data centre.
Her specialties are in news, thought leadership, features, white papers, and PR writing, and she is an experienced editor for both print and online publications. She is also a regular writer at Bora.